Research & Writing
Model reports, engineering lessons, and the occasional personal system that got too useful not to write down.
Start here
- rivet-1b: training a small model from scratch An end-to-end model build, from tokenizer and corpus to evaluation, paper and published weights.
- When a frontier lab ships a model in your domain, benchmark it A three-domain comparison that explains why adequacy and client conventions need separate measures.
- Ledger: agentic memory for my working life A personal memory system, starting with the historical 66-item failure that changed its design.
13 articles
No articles match these filters. Clear filters or try different keywords.
- · 6 min read · Projects Ledger: agentic memory for my working life A developer-preview leadership workspace: profile asks, sourced event history, owner-approved goals and scheduled agent workflows, with macOS and web clients.
- · 7 min read · Evaluation When a frontier lab ships a model in your domain, benchmark it NVIDIA shipped a strong 4B translation model. We benchmarked it against our customer-tuned models on three client domains. The result says more about metrics than about models.
- · 13 min read · Evaluation Designing new metrics to define model success. Traditional metrics are not keeping up with modern model progression. How do we tackle this, and how is arbitr pushing bringing generation evaluation into the future.
- · 3 min read · Models rivet-1b: training a small model from scratch A backdated note on rivet-1b, a 1.09B parameter model trained locally from tokenizer to post-training, with paper and weights published.
- · 5 min read · Models IBM Think 2026 - Boston The conversation at Think, across sessions, hallway conversations, and the people building on the platform, reinforced something we've been believing for a while: the era of "one large model to do everything" is (or arguably, already has) giving way to something more nuanced.
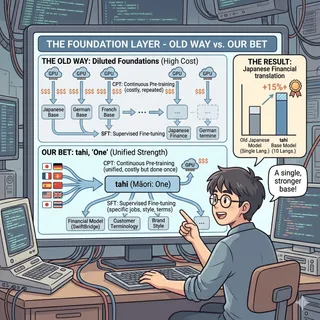
- · 6 min read · Models The Foundation Layer Earlier this year we stopped building one base model per language and trained a single one across ten. We call it tahi, "one" in Māori, because it's the first of the family and the thing every model after it stands on.
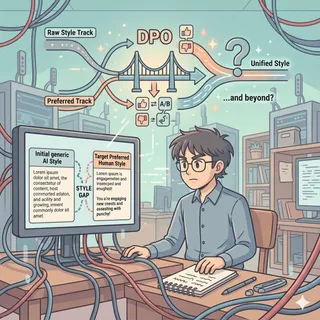
- · 4 min read · Models Closing the Style Gap - RL, DPO, and beyond It isn't always about accuracy for a translation - it's about domain-specific "vibe."
- · 5 min read · Infrastructure Why We're Researching a Fast-Path System for Live Interpretation Real-time interpretation is one of those problems that sounds solved until you actually try to build it for production.
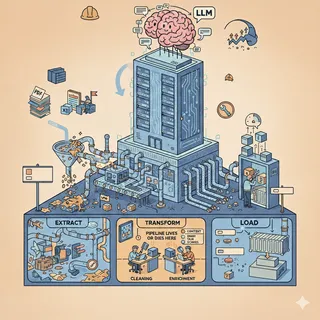
- · 9 min read · Infrastructure The Unsung Hero of AI - Why Your LLM Is Only as Good as Your Data Pipeline "Nothing could fix the building's flawed foundation." – Enter Shikai
- · 6 min read · Infrastructure ZeRO Strategies for Scaled Model Training: A Quick Look A Technical Deep-Dive into DeepSpeed ZeRO Performance Characteristics for training AI Systems
- · 4 min read · Infrastructure AI Hardware is a Tale of Two Tools Apple or Linux for AI development? An age old question, or a simple answer?
- · 4 min read · Evaluation When Your AI Model Works Better Than You Think A Translation Model Discovery Story
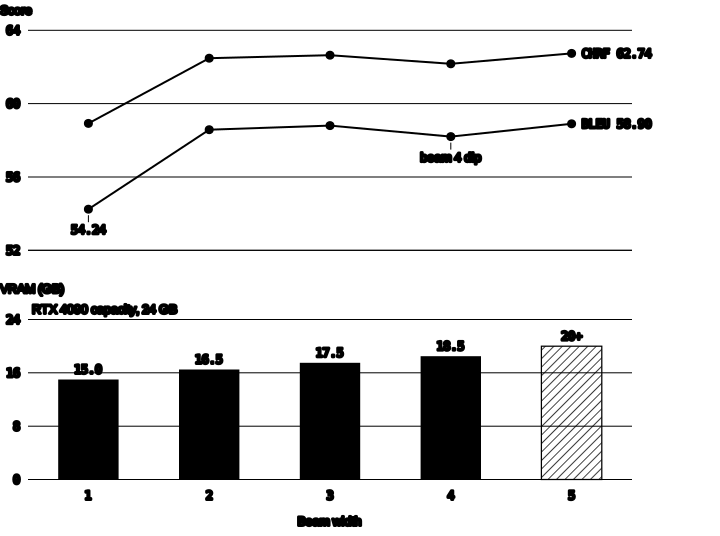
- · 5 min read · Evaluation Effects of beam search on translation quality and resource consumption A Study of Quality and Resource Tradeoffs in Straker Tiri Models